 NewOmniHuman v2 is live on imageat
OmniHuman v2
One photo. Any voice.
Upload a photo and an audio file, and ByteDance's OmniHuman v2 makes the person in it talk or sing, with lip sync, expressions and gestures that follow the voice. From 4 seconds to 5 minutes, for real people, cartoon characters and even paintings.
Every video on this page was generated with OmniHuman v2 on imageat from one image and one audio file
Photo + audio = video
There is no script to write and no length to pick. OmniHuman v2 reads the voice in your audio and animates the photo to match it: mouth shapes, eyebrows, nods and hand gestures, for exactly as long as the audio runs. Turn the sound on.
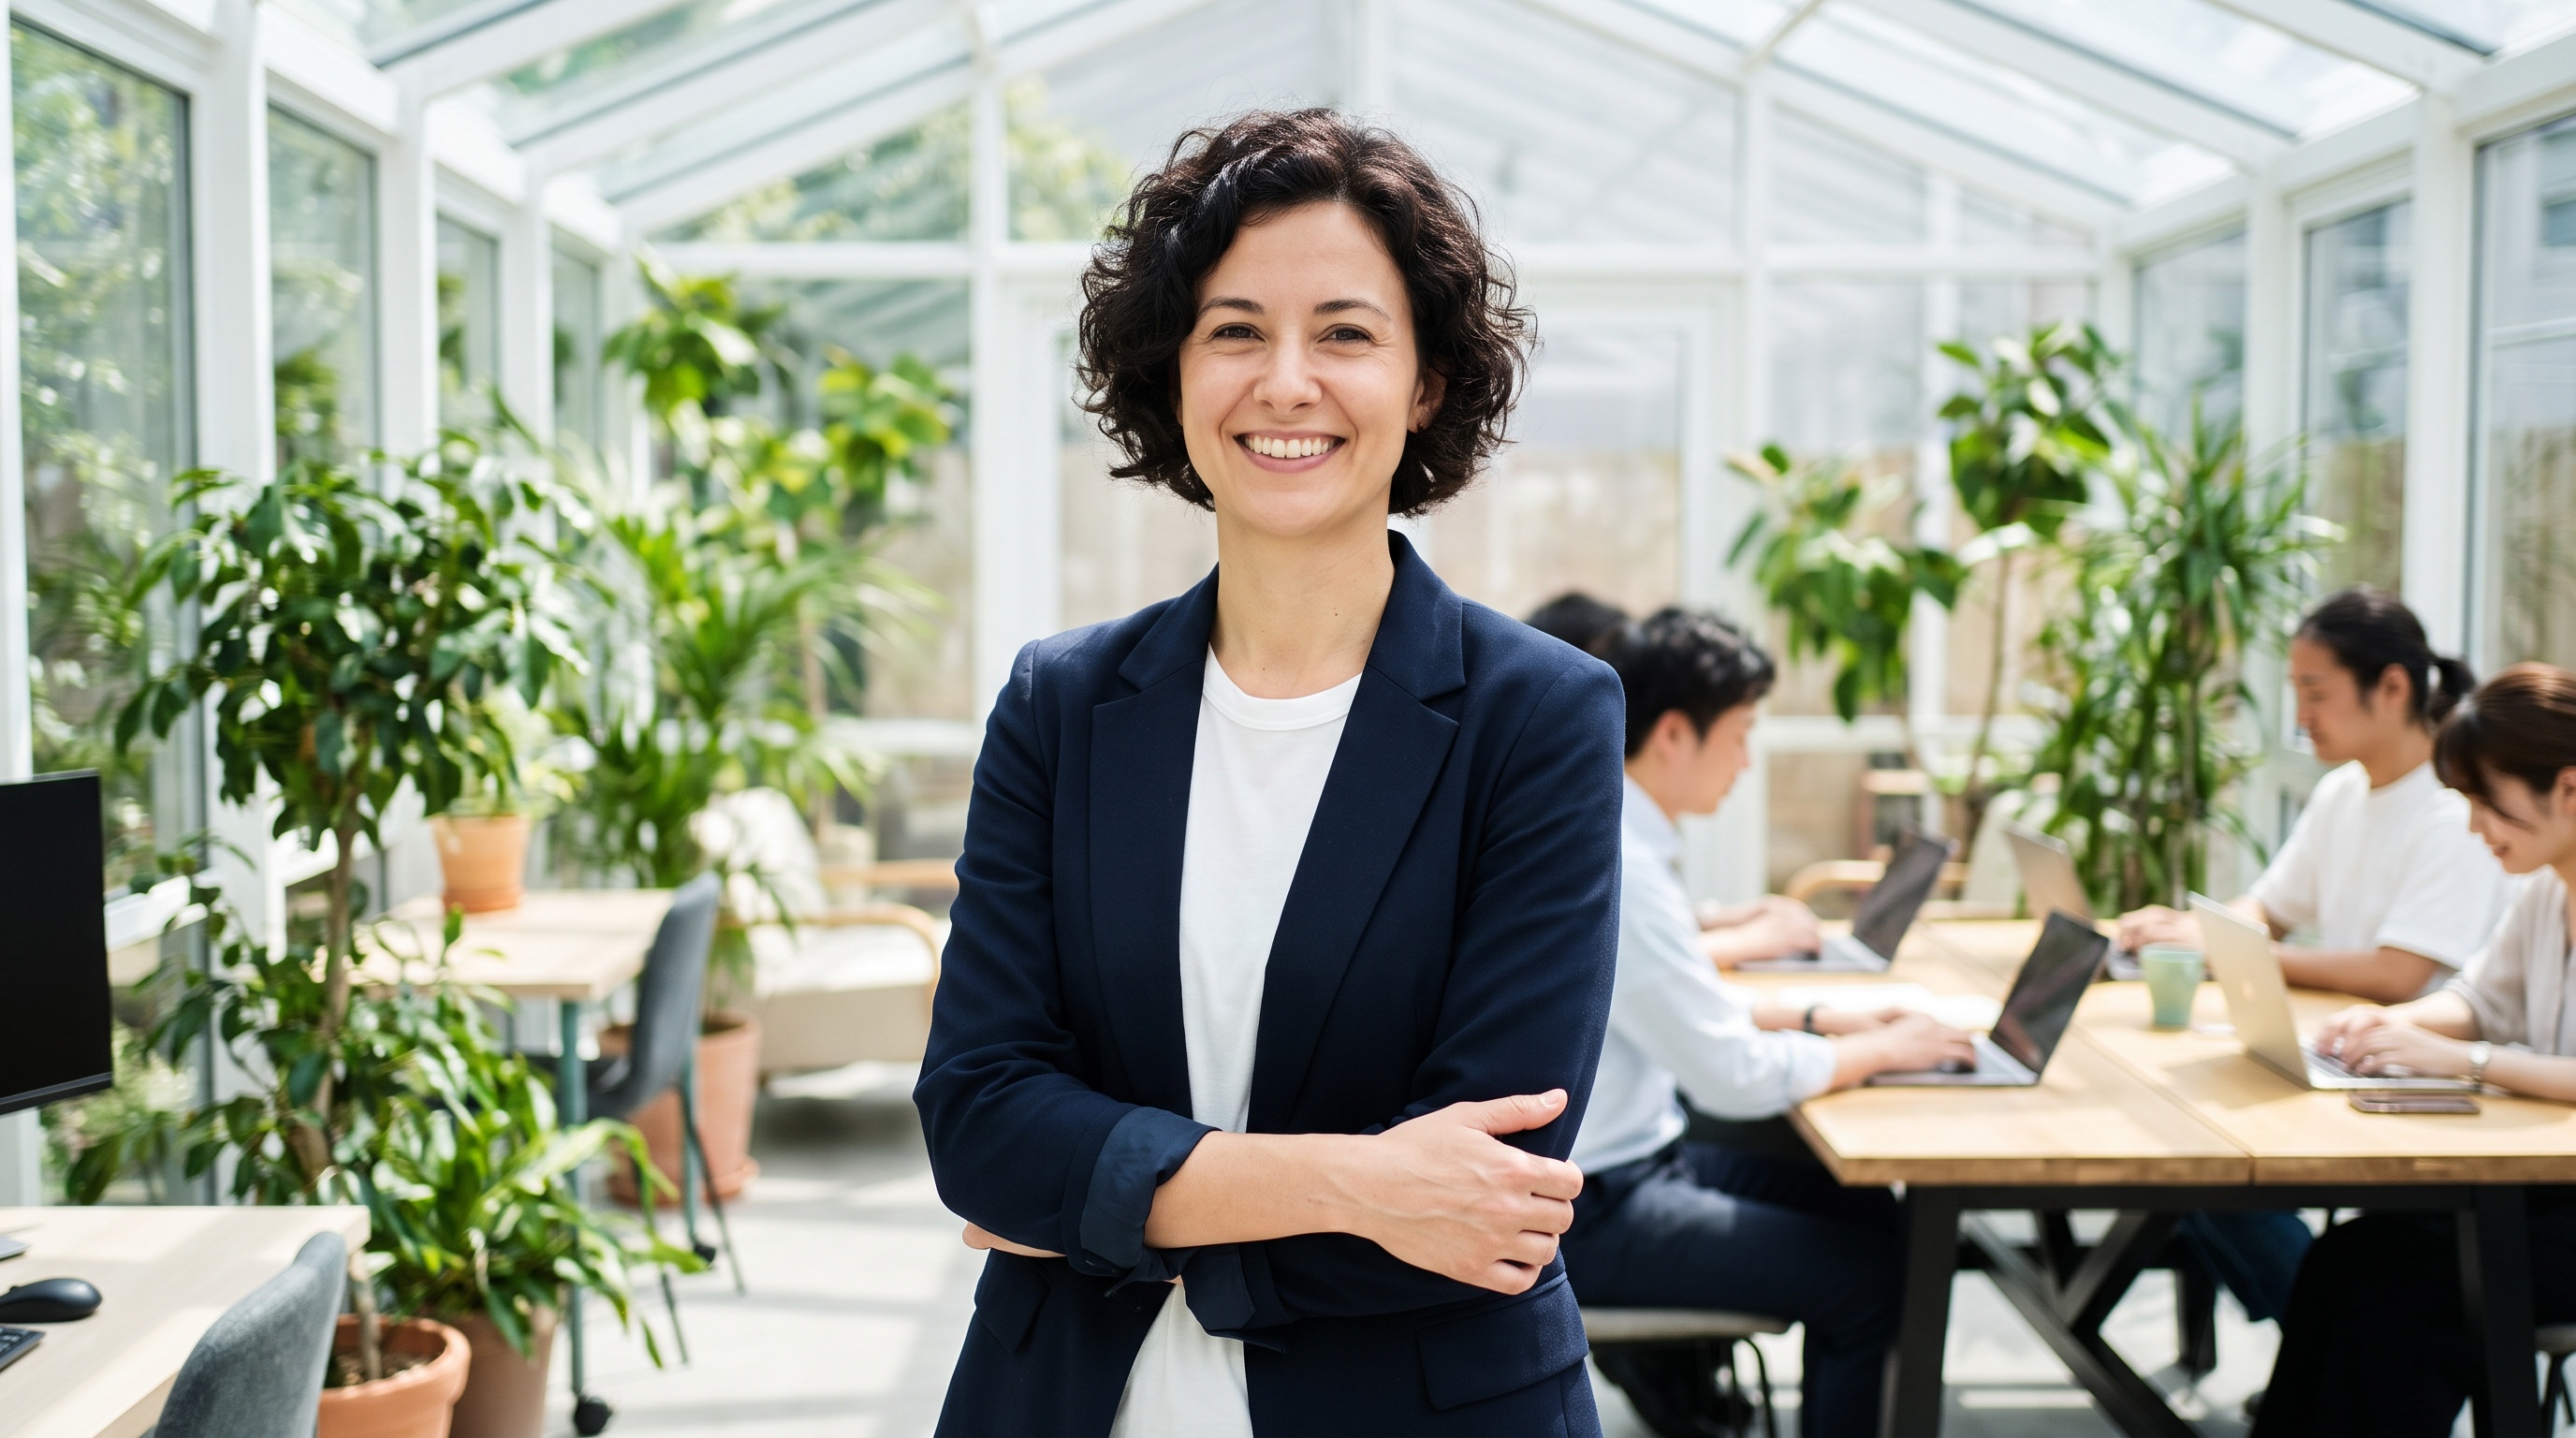 1 · Your photo
“Three years ago we were five people in a garage. Today, over two million teams plan their week with us. And honestly? We are just getting started.”
It sings, too. In any language.
Upload a song and the character sings it, breathing and swaying with the music. The lip sync follows the sound of the voice rather than a transcript, so Spanish, Turkish, Japanese or any other language works the same way.
Singing. She sings passionately into the microphone, swaying gently with the music, emotional expression.
Any language. “Bienvenidos a un nuevo episodio. Hoy tenemos una invitada increíble que nos va a contar cómo dejó su trabajo para viajar por el mundo.”
Not just real people
OmniHuman v2 animates the person in the image and keeps its style: a 3D animated hero, an anime character, an oil portrait or a selfie for an ad.
Start Now!How to use OmniHuman v2
Upload a photo
A person or character with the face clearly visible. Or pick one of your saved characters with @.
Add the audio
An MP3 or WAV of the speech or song, 4 seconds to 5 minutes. Optionally describe gestures or camera.
Generate and download
OmniHuman v2 renders a lip-synced video exactly as long as the audio. Download the MP4 from your history.
Everything OmniHuman v2
can do on imageat
| Input | One image plus one audio file, and an optional text prompt |
|---|---|
| Image | JPG, PNG, WebP and more, 300 to 6,000 px per side, aspect ratio between 0.4 and 2.5 |
| Audio | MP3 or WAV, 4 seconds to 5 minutes, up to 15 MB, in any language |
| Length | Matches the audio exactly, rendered in one generation |
| Framing | Follows your image: vertical, square or landscape |
| Prompt | Optional, for gestures, expression and camera. English, Chinese, Japanese, Korean, Mexican Spanish and Indonesian |
| Output | MP4 with your audio, saved to your history |
Tips for the best lip sync
Face the camera
A clear, well-lit human face looking roughly toward the camera gives the most accurate lip sync. Animal characters are not supported.
Leave room to move
Upper-body photos with visible hands get natural gestures; tight face crops mostly move the head.
Clean audio
A dry voice recording beats one buried under music. For songs, use a mix where the vocal is clear.
Direct it
Add a short prompt for the movement you want: "leans in and laughs", "slow push-in on her face".
Made with OmniHuman v2
Each clip with the photo it started from and what the audio says.
Founder pitch
“Three years ago we were five people in a garage. Today, over two million teams plan their week with us. And honestly? We are just getting started.”
Make your ownCreator review
“Okay, you guys asked, so here it is. This is the serum I have used every single night for a month, and my skin has literally never looked better.”
Make your ownPodcast in Spanish
“Bienvenidos a un nuevo episodio. Hoy tenemos una invitada increíble que nos va a contar cómo dejó su trabajo para viajar por el mundo.”
Make your ownAnimated explorer
“Hey there, explorer! Ready for an adventure? Grab your map, because today we are finding the secret waterfall!”
Make your ownA painting that talks
“For two hundred years I have hung upon this wall in perfect silence. And now, at last, somebody has given me a voice. How delightful.”
Make your ownPay per second of audio
The price follows your audio length and is shown before you generate. One credit is $0.10, and failed videos are refunded automatically.
Make the voice first
OmniHuman v2 needs a recording to follow. Record yourself, export a voiceover, or generate the voice and the song on imageat, then bring the MP3 into the video studio.
Give your photo
a voice
OmniHuman v2 sits in the imageat video studio next to Wan, Seedance, Kling and Veo. Upload a photo, add the audio, and pay only for the seconds you generate.
Questions, answered
OmniHuman is developed by ByteDance. imageat is not affiliated with ByteDance.